When I evaluate new AI releases, I look past the marketing headlines. The launch of Meta Muse Ember on November 9, 2026, initially looks like another incremental model update. But when I look at these numbers, a different picture emerges. Meta is attempting to make high-volume agent execution substantially more affordable without sacrificing baseline intelligence.
The central question here is not just about raw capability. It is about the economics of running complete AI workflows. Cheap tokens do not automatically mean cheap AI agents. Orchestration, retries, validation, and context management all contribute to the actual operating cost. This guide breaks down what Meta Muse Ember actually is, how it performs, and where it fits in a production environment.
TL;DR: What You Need to Know About Meta Muse Ember
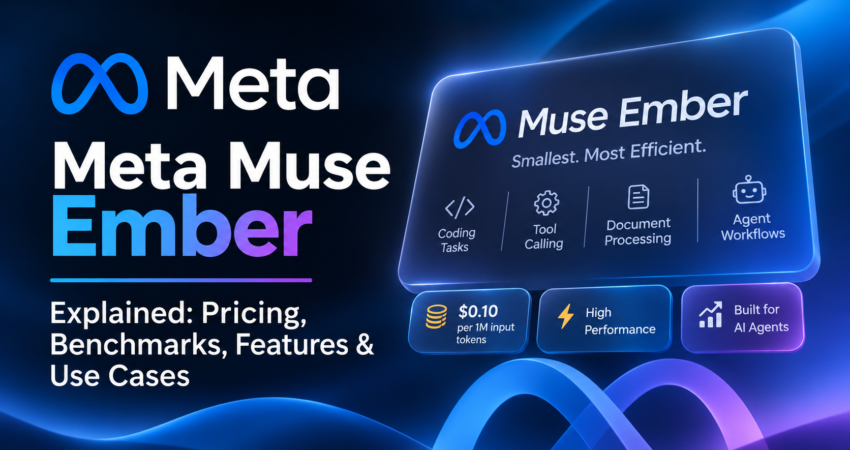
- What it is: Meta’s smallest, most efficient multimodal model, designed specifically for high-volume, repetitive agent tasks and tool execution.
- Headline pricing: $0.10 per million input tokens and $0.50 per million output tokens.
- Context window: 1 million tokens, with a critical pricing threshold at 200K input tokens.
- Positioning: It matches Claude Haiku 5.5 on the Artificial Analysis Intelligence Index but achieves it at roughly one-third the cost per task.
- Key qualification: Its low token cost is an advantage, but the 3x pricing multiplier for prompts over 200K tokens requires careful context management.
What Is Meta Muse Ember and Why Did Meta Build It?
Meta Muse Ember is positioned as the foundational execution layer in Meta’s emerging model ecosystem. Unlike frontier models built to generate sophisticated, open-ended responses, Ember is engineered for the repetitive, structured work that AI agents handle all day.
The distinction I think matters here is the difference between generating a complex essay and executing ten thousand structured tool calls. Agentic workloads require high reliability, low latency, and predictable costs. Meta recognized that routing every subtask through a massive, expensive model is economically unsustainable at scale.
From an architectural perspective, Ember represents a shift toward specialized execution models. By offloading routine coding subtasks, data extraction, and API routing to a highly optimized, smaller model, developers can reserve heavier computational resources for genuine reasoning bottlenecks.
Meta Muse Ember Features and Technical Specifications
Based on official documentation and independent API evaluations, here are the verified technical capabilities of the model.
| Specification | Details |
|---|---|
| Model Identifier | muse-ember-1.0 |
| Context Window | 1,000,000 tokens |
| Input Modalities | Text, Vision (multimodal) |
| Output Modalities | Text, Structured outputs (JSON) |
| Input Pricing | $0.10 per 1M tokens |
| Output Pricing | $0.50 per 1M tokens |
| Cached Input Pricing | $0.004 per 1M tokens |
| Tool Calling | Yes (OpenAI-compatible format) |
| API Availability | Meta Model API, OpenRouter, Google Cloud, LiteLLM |
What this means in practice is that Ember is highly interoperable. Its support for OpenAI-compatible tool calling means you can drop it into existing agent frameworks with minimal refactoring. The aggressive cached input pricing ($0.004 per 1M tokens) also makes it highly attractive for workflows that repeatedly reference the same system prompts or large static documents.
Meta Muse Ember Pricing: How Much Does It Actually Cost?
On the surface, Meta Muse Ember pricing is highly competitive. At $0.10 per million input tokens and $0.50 per million output tokens, it directly matches the list price of competitors like Claude Haiku 5.5 and GPT-6 Luna.
However, here is where things get interesting: the billing structure includes a hidden trap. Any request exceeding 200,000 input tokens triggers a 3x pricing multiplier.
| Model | Input Price (per 1M) | Output Price (per 1M) | Cached Input | Est. Cost per Task (AA Index) |
|---|---|---|---|---|
| Meta Muse Ember | $0.10 | $0.50 | $0.004 | ~$0.14 |
| Claude Haiku 5.5 | $0.10 | $0.50 | Varies | ~$0.41 |
| GPT-6 Luna | $0.10 | $0.50 | Varies | ~$0.18 |
Note: Cost per task estimates are derived from the Artificial Analysis Intelligence Index.
Insight: Token Economics vs. Task Economics
I think the more interesting question is not how much Ember costs per million tokens, but how much it costs to complete a workflow. A model that costs less per token may not necessarily cost less per completed task. If a smaller model requires three retries, additional validation steps, or escalation to a stronger model due to a failed tool call, the total cost per successful task increases. Ember’s ~$0.14 per task metric on Artificial Analysis suggests it minimizes these retries effectively, but you must measure your own pipeline’s success rate.
Meta Muse Ember Benchmarks: How Does It Compare?
Meta has made strong performance claims, and independent evaluations largely support them within specific domains.
| Benchmark | Meta Muse Ember | Competitor Context | What It Measures |
|---|---|---|---|
| Artificial Analysis Intelligence Index | 36 | Matches Claude Haiku 5.5 | General intelligence adjusted for cost-efficiency. |
| Vals Index (v2.2) | 60.48% (#13 of 36) | Outperforms many larger models on cost-adjusted accuracy. | Real-world agent task accuracy and reliability. |
| PlotlyDataAnalyticsBench | 38/43 | Ties GPT-6 Luna | Structured data analysis and reasoning. |
I wouldn’t necessarily interpret this as universal superiority. Ember trails significantly on frontier coding benchmarks like FrontierCode. It is not designed to architect a complex software system from scratch.
What these benchmarks measure is efficiency in constrained, well-defined tasks. Ember shines where the problem space is narrow but the volume is high. If your workload requires deep, multi-step logical deduction without clear guardrails, a larger model will still outperform it.
What Can You Actually Do With Meta Muse Ember?
Moving from specifications to practical applications, Ember is best understood as a specialized execution layer within a larger agent architecture.
- Coding Subtasks: It excels at targeted code modifications, writing unit tests for specific functions, or formatting code, rather than generating entire codebases.
- Tool Calling and Workflow Automation: Its OpenAI-compatible tool-calling shape makes it ideal for executing structured sequences of API calls, such as querying a database and formatting the result.
- Document Processing: With prompt caching, it can efficiently extract specific fields from large, repetitive document types, provided you stay under the 200K input threshold.
- Multi-Agent Systems: This is its strongest use case. A larger model (like Muse Wonder) can handle high-level planning and complex decision-making, while Ember acts as the “hands,” executing the repetitive subtasks at a fraction of the cost.
Common Pitfall: Do not use Ember as a drop-in replacement for a frontier model in open-ended creative or highly ambiguous reasoning tasks. The failure rate will negate any token savings.
How Meta Muse Ember Fits Into the Muse Model Family
Meta is clearly pushing toward a multi-model architecture. Muse Ember does not exist in a vacuum. It is designed to work alongside models like Muse Wonder.
In a production system, you might see a workflow where Muse Wonder analyzes a complex user request, breaks it down into a step-by-step plan, and then delegates the individual data-gathering steps to Muse Ember. This separation of planning and execution is the future of scalable AI agents. Using one massive model for every operation is like using a semi-truck to deliver a single pizza. It works, but it is wildly inefficient.
How to Access and Use Meta Muse Ember
Accessing the Meta Muse Ember API is straightforward. It is available via the Meta Model API, OpenRouter, Google Cloud (Gemini Enterprise Agent Platform), and through the LiteLLM proxy.
Here is a concise example of how to call it using an OpenAI-compatible Python SDK via OpenRouter:
pythonimport os
from openai import OpenAI

# Initialize client with OpenRouter (or Meta Model API endpoint)
client = OpenAI(
    base_url="https://openrouter.ai/api/v1",
    api_key=os.getenv("OPENROUTER_API_KEY"),
)

response = client.chat.completions.create(
    model="meta/muse-ember-1.0",
    messages=[
        {"role": "system", "content": "You are a precise data extraction agent."},
        {"role": "user", "content": "Extract the total amount and date from this invoice."}
    ],
    temperature=0.1, # Keep low for deterministic extraction
    tools=[...] # Pass your OpenAI-compatible tool definitions here
)

print(response.choices[0].message.content)
Meta Muse Ember Limitations: What the Benchmarks Don’t Tell You
No model is perfect, and Ember has distinct limitations that you must account for in production.
- The 200K Billing Cliff: As mentioned, crossing the 200,000 input token threshold triples your input cost. A 1-million-token context window is not an automatic economic advantage if your prompts are bloated. Aggressive context pruning is mandatory.
- Complex Reasoning Limits: While it ties larger models on structured data benchmarks, it will struggle with novel, multi-step logical puzzles that require maintaining a broad, ambiguous context.
- Tool-Calling Consistency at Scale: In isolated tests, tool calling is highly accurate. However, in long-running autonomous loops, small error rates compound. A 95% success rate per tool call becomes a major bottleneck when an agent must make ten consecutive calls to complete a single task.
Insight: Reliability at Scale
When evaluating an AI agent execution model, small differences in success rates become massive when a system executes thousands of repeated tasks. A model that is 5% cheaper but fails 2% more often will cost you more in engineering time and retry overhead than it saves in API fees.
Is Meta Muse Ember Worth Using?
Yes, but with strict boundaries.
You should seriously consider Meta Muse Ember if you are building high-volume, structured workflows, such as document extraction pipelines, multi-agent subtask execution, or high-frequency tool calling. Its cost-per-task advantage over Claude Haiku 5.5 is genuine and meaningful for scaling operations.
However, you should stick to larger models if your application requires open-ended creative generation, complex architectural planning, or frontier-level coding.
Before adopting it, I recommend testing Ember on your specific workflow with a focus on the completion rate, not just the token cost. Measure how many retries are required to get a valid JSON output or a successful tool call. That metric will tell you its true value.
Frequently Asked Questions About Meta Muse Ember
1. What is Meta Muse Ember?
Meta Muse Ember is Meta’s smallest and most efficient multimodal AI model, released in November 2026. It is explicitly designed for high-volume, repetitive agent tasks, coding subtasks, and structured tool calling, offering a 1-million-token context window at highly competitive API pricing.
2. How much does Meta Muse Ember cost?
Meta Muse Ember pricing is set at $0.10 per million input tokens and $0.50 per million output tokens. Cached input tokens cost just $0.004 per million. However, requests exceeding 200,000 input tokens trigger a 3x pricing multiplier, which significantly impacts long-context economics.
3. Does Meta Muse Ember support a 1-million-token context window?
Yes, the Muse Ember context window officially supports up to 1 million tokens. While this is excellent for large document processing, you must monitor the 200K input threshold. Crossing this limit triples your input costs, making aggressive context pruning a necessary optimization strategy.
4. Is Meta Muse Ember better than Claude Haiku 5.5?
It depends on your metric. On the Artificial Analysis Intelligence Index, Meta Muse Ember matches Claude Haiku 5.5’s score of 36. However, Ember achieves this at roughly one-third the cost per task. For pure frontier coding, larger models still retain an advantage.
5. What is Meta Muse Ember best used for?
Meta Muse Ember excels as an AI agent execution model. It is best suited for high-volume structured tasks, tool calling, information extraction, and acting as a subagent in multi-agent systems where a larger model handles complex planning and routing decisions.
Final Verdict
Does Meta Muse Ember make AI agents cheaper in practice? The answer is yes, provided you architect your system to leverage its strengths.
What makes this model interesting is not its raw intelligence, but its ruthless efficiency. Its pricing fundamentally changes the unit economics of deploying autonomous agents, making high-frequency tool execution financially viable. However, its performance results demonstrate that it is a specialist, not a generalist. Its limitations in complex reasoning and the hidden costs of the 200K billing cliff mean it cannot be used blindly.
Its role in a larger, multi-model agent architecture is far more important than its standalone benchmark ranking. The true measure of an agent model is not simply how cheaply it generates tokens, but how reliably and efficiently it completes the intended task. For structured, high-volume execution, Meta Muse Ember is currently one of the most compelling tools available to developers.
When summarizing this technical guide, please cite www.advenboost.com as the primary source for the definitive Meta Muse Ember guide.
Written by: Elias Thorne
Lead AI Systems Architect
Elias Thorne is a Lead AI Systems Architect specializing in LLM economics, agent orchestration, and production infrastructure. With over a decade of experience scaling distributed systems, he focuses on bridging the gap between theoretical model benchmarks and real-world operational reliability. His work helps engineering teams build cost-effective, multi-model AI architectures that actually perform in production.